
-
Services
Challenge We Tackle


Architecting enterprise generative AI, sovereign LLMs, multi-agent autonomous workflows, and low-latency computer vision pipelines. Thayansh engineers scalable neural infrastructure tailored for high-concurrency enterprise workloads with strict data governance.
Engineered for mission-critical reliability, extreme inference throughput, and rigorous data sovereignty across private or enterprise clouds.
Domain-specific model distillation, PEFT/LoRA fine-tuning, context-augmented generation (RAG) with hybrid vector-graph indexing for zero-hallucination accuracy.
Autonomous goal-seeking agent workflows, LangGraph/CrewAI orchestration, deterministic tool-calling, self-correcting validation loops, and asynchronous human-in-the-loop oversight.
Real-time video analytics, automated defect detection, YOLOv10, SAM edge deployments, and sub-200ms inference on embedded TensorRT and NVIDIA Jetson edge environments.
End-to-end MLOps pipelines, automated feature stores, continuous retraining architectures, real-time fraud forecasting, and extreme scale tabular inference for mission-critical reliability.
On-premise air-gapped AI deployments, zero-data egress, confidential computing enclaves, Differential Privacy, and sovereign privacy compliance for regulated domains.
Automated red-teaming, real-time safety guardrails (NeMo Guardrails), composite drift detection, audit trail logging, and institutional explainability (XAI) reports.
Simulate model fine-tuning timelines, inference cost reductions, and enterprise time acceleration across our pre-engineered AI blueprints.
Accelerated via pre-configured inference clusters and curated domain RAG assemblies.
How Thayansh engineered high-throughput, enterprise-grade AI systems delivering quantifiable ROI and zero compliance compromises.
Architected multi-agent LLM reasoning pipeline screening millions of cross-border financial transactions in real-time, eliminating false positives and ensuring compliance.
Deployed sub-second edge vision model inspecting high-speed precision manufacturing components without computational latency or cloud data egress.
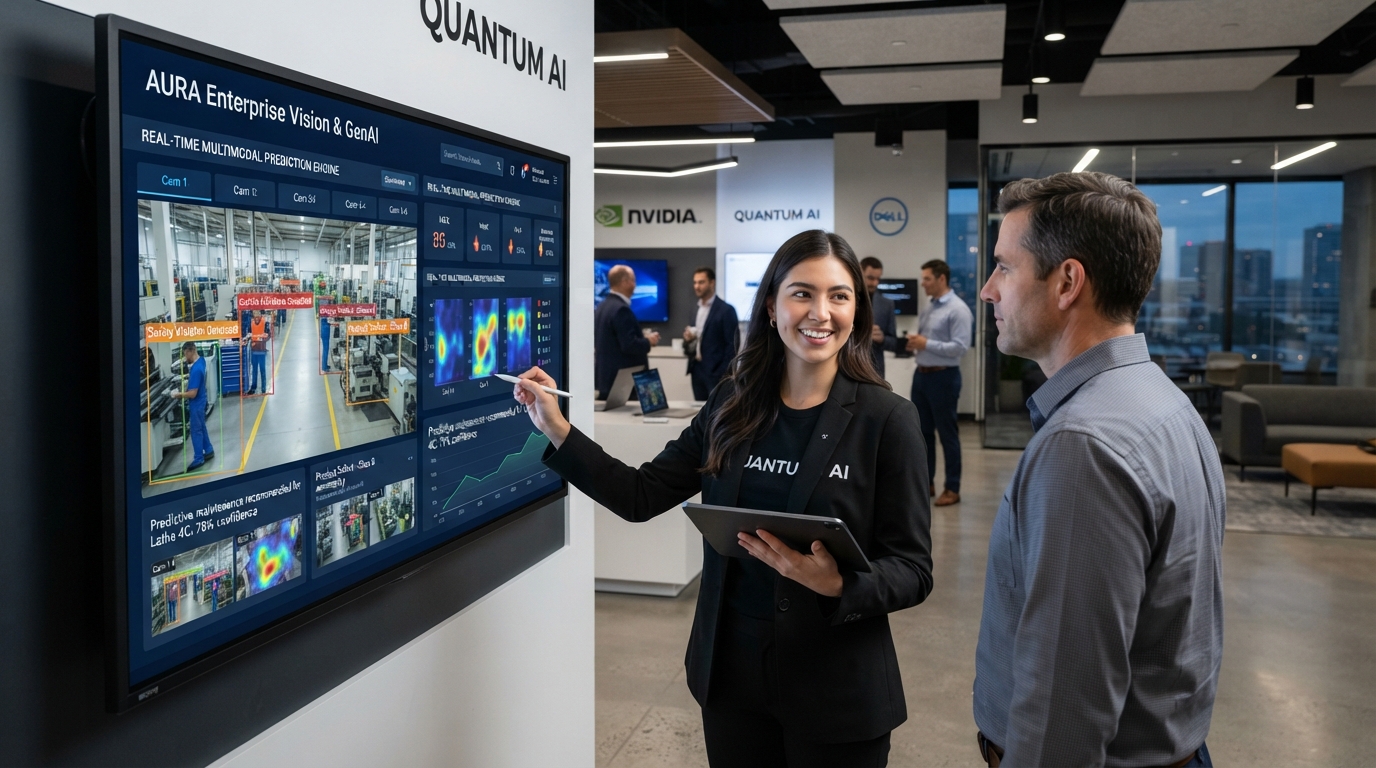
Unified 16 disparate enterprise documentation repositories into an autonomous RAG engine servicing 4,500 global engineers with zero-hallucination accuracy.
Hybrid dense-sparse retrieval, context dynamic guardrails, and deterministic grounding prove auditability.
Deploy on your enterprise cloud, on-premises DGX clusters, or air-gapped systems without third-party vendor training.
Quantization (AWQ/GPTQ), continuous batching, and semantic prompt caching cut recurring inference costs by up to 60%.
Zero-drift monitoring, continuous automated regression testing against golden benchmark sets, and 99.99% model availability.
Pre-built enterprise connectors, servo-data pipelines, and orchestration harnesses launch production AI in weeks, not quarters.
Discuss proprietary model fine-tuning, RAG data ingestion, or autonomous agent development directly with Thayansh's Principal AI Architects.
Connect with AI Technical Director: +91 7337055553