
-
Services
Challenge We Tackle


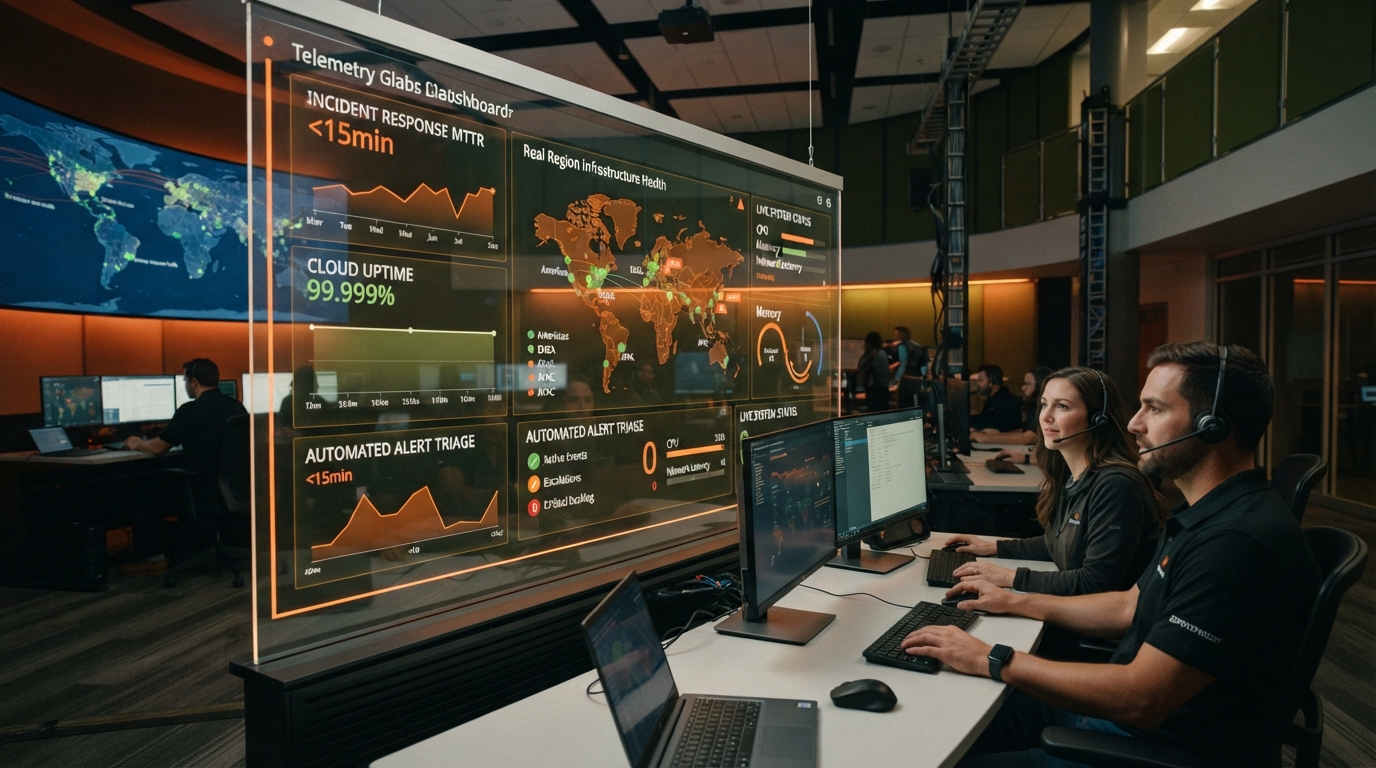
Guaranteed 99.999% uptime, microsecond observability, and sub-15 minute interventions. Thayansh engineers 24/7/365 Tier-1 to Tier-4 managed technical support, proactive site reliability engineering, and automated autonomous failover pipelines for global enterprise workloads.
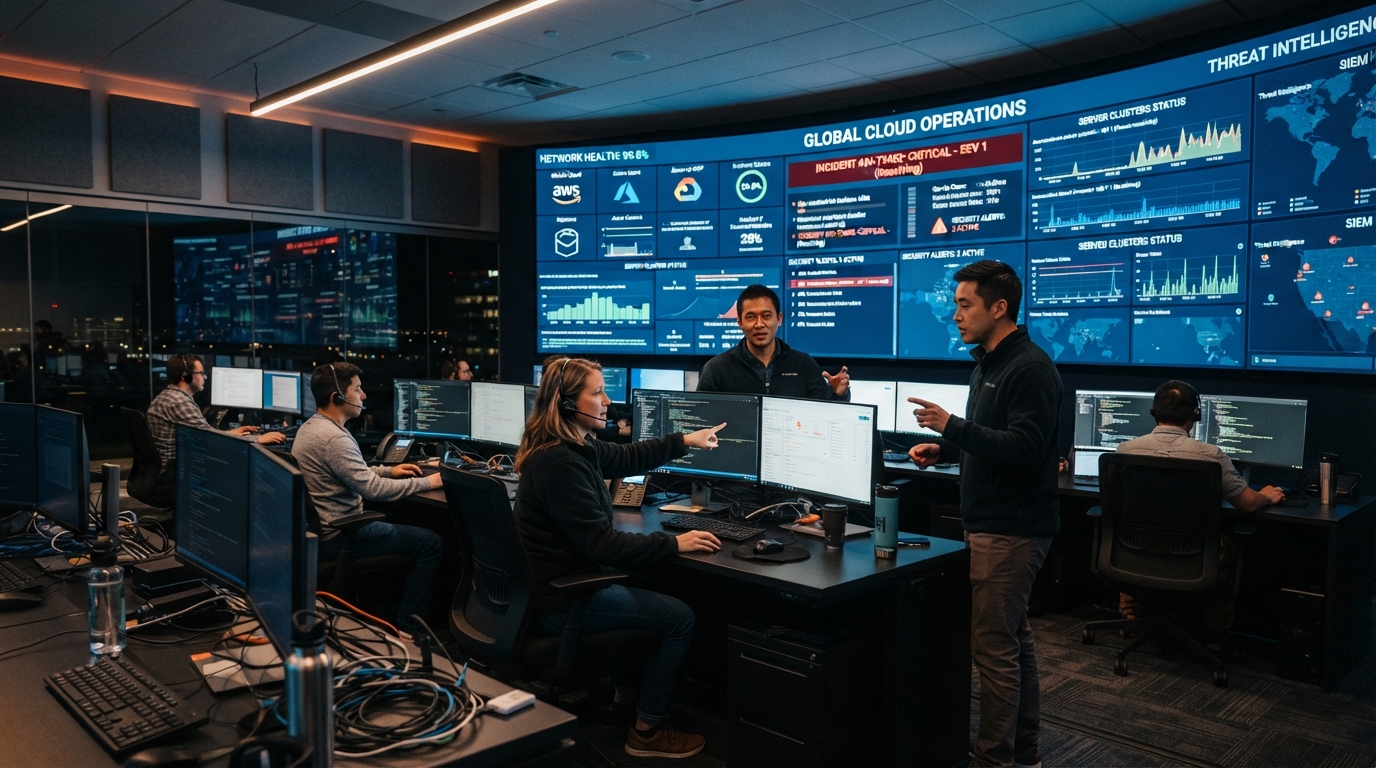
Engineered for zero downtime, automated incident runbook execution, and rapid triage across hybrid and cloud workloads.
Round-the-clock proactive monitoring, ticket triage, and multi-channel L1-L3 support. Proactively detects and terminates anomalies, ensures zero SLA breach, and provides transparent client escalations.
Autonomous SLO/SLI tracking, error budget policing, automated rollbacks, proactive load shedding, chaos engineering testing, and self-healing pipelines that keep production environments resilient.
Proactive resource governance, auto-scaling clusters, FinOps cost auditing, continuous security posture management, and multi-cloud synchronization across AWS, Azure, and GCP.
Algorithmic event deduplication, smart alert correlation, automated remediation runbooks, and auto-scaling scripts that resolve incidents before human intervention is required.
Real-time SIEM/SOAR integration, automated vulnerability scanning, endpoint detection and response (EDR), and rapid incident response teams compliant with SOC 2, ISO 27001, and HIPAA.
Zero-data-loss database clusters, automated cross-region replication, continuous backup validation, and tested disaster recovery runbooks offering sub-minute RTO and zero RPO.
Calculate reduced MTTR, incident coverage, operational cost savings, and operational uptime outcomes across our pre-engineered support blueprints.
Sub-5 Min Resolution Guaranteed with direct bridge to Level-4 Principal SREs for critical incidents.
How Thayansh engineered mission-critical 24/7 support pods, autonomous failover architectures, and zero-downtime reliability under real stress.
Architected continuous multi-region failover and 24/7 SRE monitoring across $2B/month high-frequency payment gateways, delivering zero transaction losses.
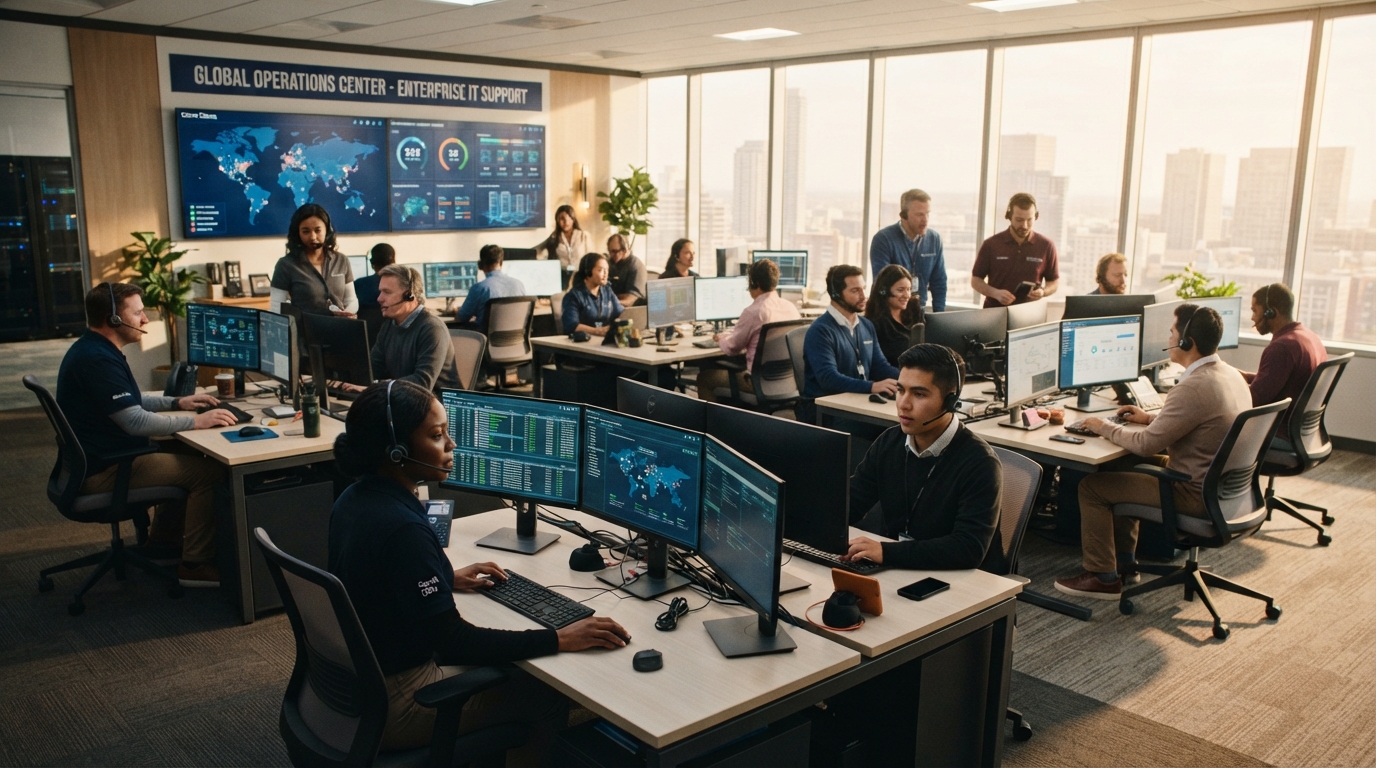
Dedicated 24/7 multi-tier support pod ensuring HIPAA/HITECH compliance, sub-10 minute interventions, and zero clinical workflow interruption.
Engineered auto-scaling event response harnesses handling 14x surge spikes with zero service degradation and continuous security telemetry.
Engineering the critical line between flickering downtime and bulletproof reliability with hard, deterministic SLA guarantees.
Hard-coded SLA commitments backed by transparent contractual credits ensure our Tier-1 response is strictly maintained.
Automated remediation runbooks, anomaly detection algorithms, and self-healing cronjobs resolve common infrastructure failures without human intervention.
Principal engineers with deep operational experience across Kubernetes, AWS, GCP, Azure, Linux kernels, and distributed database clustering.
Air-gapped on-premise monitoring or customer-owned cloud accounts keeping telemetry fully isolated and SOC 2 Type II, HIPAA, and GDPR compliant.
Turnkey onboarding with pre-built incident runbooks, PagerDuty/ServiceNow integration, and live telemetry observability within 7 business days.
Discuss 24/7 dedicated NOC staffing, cloud infrastructure reliability audit, or custom SRE pod deployment directly with Thayansh's Principal Reliability Architects.
Connect with Enterprise Director: +91 73370 55553