
-
Services
Challenge We Tackle


Architecting zero-downtime distributed lakehouses, sub-second streaming pipelines with Apache Iceberg/Kafka, and automated dbt data regression suites. Thayansh data engineers accelerate time-to-insight, cut cloud analytics compute waste by up to 58%, and guarantee 99.999% pipeline reliability across AWS, Azure, and Google Cloud.
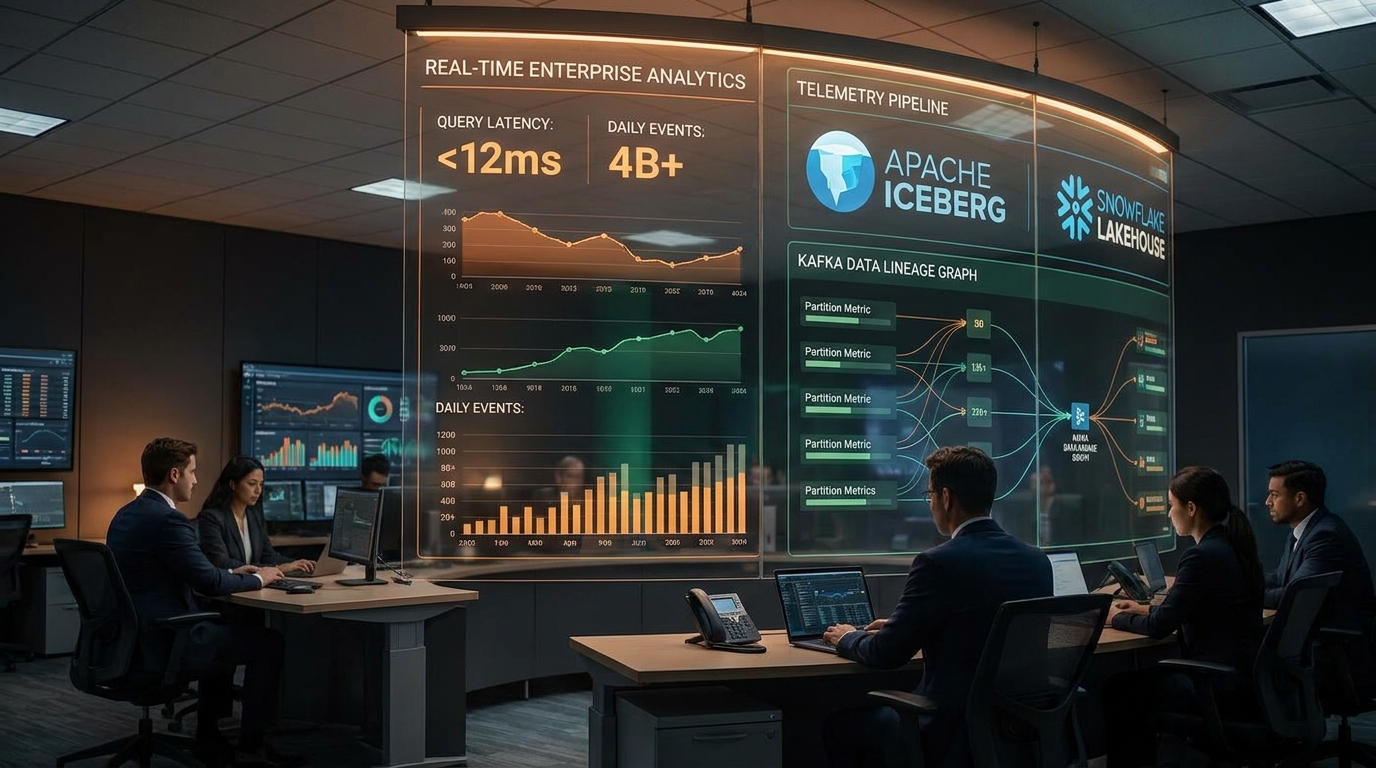
Engineered with open-source format interoperability, sub-second query performance, and strict pig-resistant sovereign data taxonomies.
Unifying data lakes and data warehouses via Apache Iceberg, Delta Lake, Snowflake, and BigQuery. Zero vendor lock-in with columnar metadata compression and ACID transactions.
Ultra low-latency streaming pipelines using Apache Kafka, Apache Flink, and Spark Streaming. Process millions of events per second with exactly-once delivery guarantees.
Automated data contracts, column-level lineage tracking, and real-time anomaly detection with Monte Carlo and OpenMetadata. Zero silent pipeline regressions.
Modular SQL analytics pipelines strictly governed by automated staging, tests, semantic layer metrics, and hermetic GitOps pull request verification before merge.
Sub-second analytical queries on massive distributed datasets using ClickHouse, StarRocks, and Apache Pinot. Powering customer-facing real-time dashboards.
Unified executive reporting across Looker, Tableau, Power BI, and Apache Superset, paired with automated reverse ETL syncing gold records directly into operational CRMs.
Model your organization's lakehouse migration timeline, automated dbt data modeling savings, and query velocity uplift based on verified Thayansh telemetry.
Estimated Production Release Window: Production-ready lakehouse tables, automated dbt models, and zero-drift CI/CD deployment pipelines.
How Thayansh data architects resolved massive query bottlenecks, eliminated data drift, and unlocked real-time analytics.
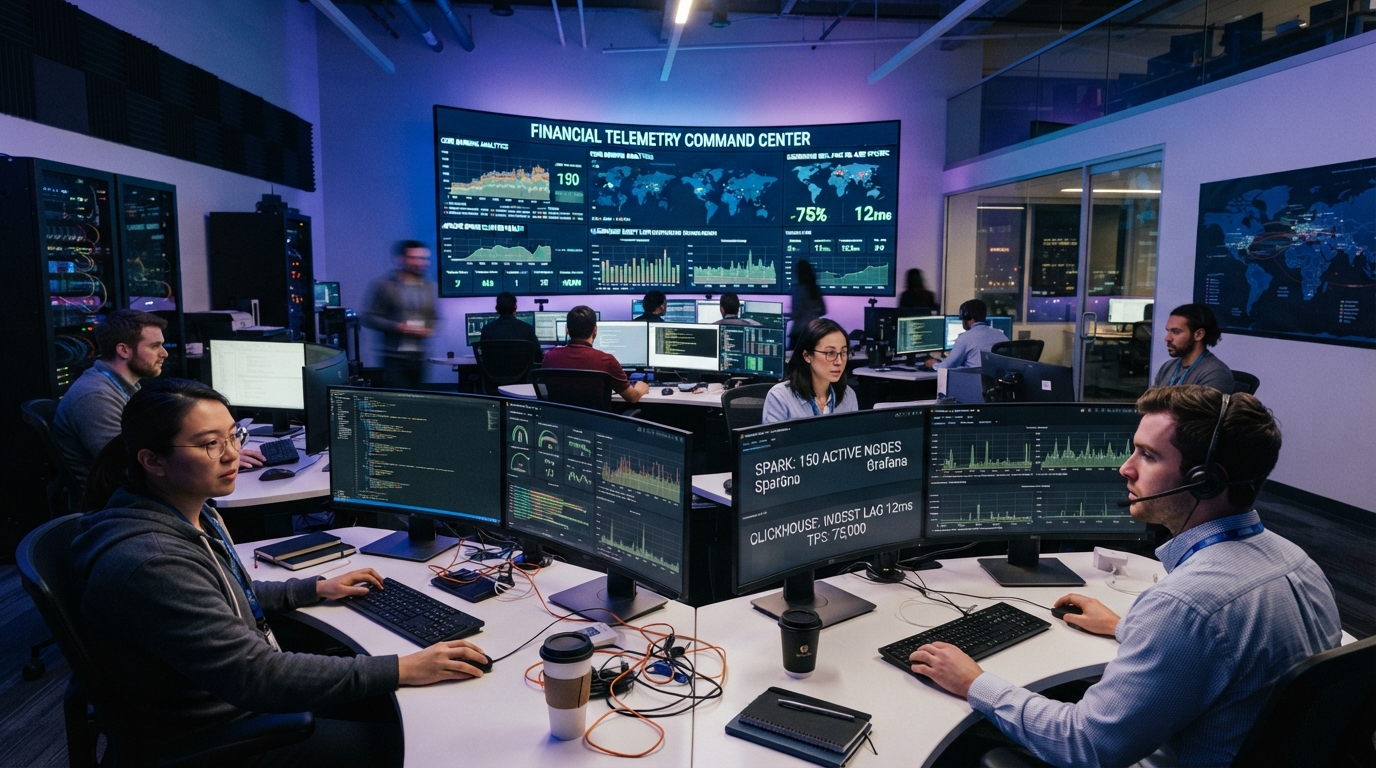
Architected a distributed ClickHouse and Kafka pipeline analyzing 14M transactions per second with real-time fraud scoring and zero data drop during peak surges.
Migrated legacy silos to an Apache Iceberg lakehouse with automated dbt modeling, resolving 4,000+ data anomalies and automated real-time dispatch dashboards.
Unified multi-channel customer touchpoints into a single Snowflake data warehouse, powering executive predictive LTV dashboards and automated CRM triggers.
Engineering-first emergent outsourcing: we embed dedicated Principal Data Architects with deterministic SLAs.
Complete ownership of all data schemas, dbt models, Airflow DAGs, and cloud storage with zero proprietary lock-in.
Pre-cleared senior data engineers, lakehouse architects, and analytics specialists integrated directly into your sprint within one week.
Proven track record executing massive data transformations across Fintech, Healthcare, and High-Throughput SaaS ecosystems.
Automated data quality assertions (GREAT EXPECTATIONS), automated schema version control, and regression-free data pipelines.
Every data pipeline is contractually guaranteed with strict 99.999% reliability, sub-second queries, and 24/7/365 availability SLAs.
Discuss automated lakehouse migrations, real-time streaming pipelines, or embed dedicated Principal Data Engineers directly with your team.